How AI Use Cases Get Selected Today
Walk into any large enterprise and ask for the list of AI initiatives. You will get a spreadsheet, assembled last quarter for a steering committee, already stale. It will contain somewhere between twenty and eighty rows. Ask a second question, “why these?”, and the answers fall into three buckets: an executive sponsored it, a vendor demoed it, or a team was already experimenting and got grandfathered in.
None of those are selection criteria. They are acquisition stories. Nobody chose the portfolio. It accumulated, one sponsored ticket at a time.
This is the use-case lottery. Every business unit buys a ticket, funding flows to the tickets held by the best-connected sponsors, and the organization waits to see which ones pay out. Lottery economics follow. A few wins get amplified in internal communications, the losses persist quietly as zombie pilots, and nobody can say what the portfolio as a whole is worth, because it was never constructed as a portfolio.
The Missing Discipline Is Selection, Not Execution
The standard diagnosis for weak AI results is execution: not enough talent, immature platforms, poor data. Execution problems are real, but they sit downstream of a selection problem that rarely gets named. If the use case should never have been funded, no amount of engineering rescues it.
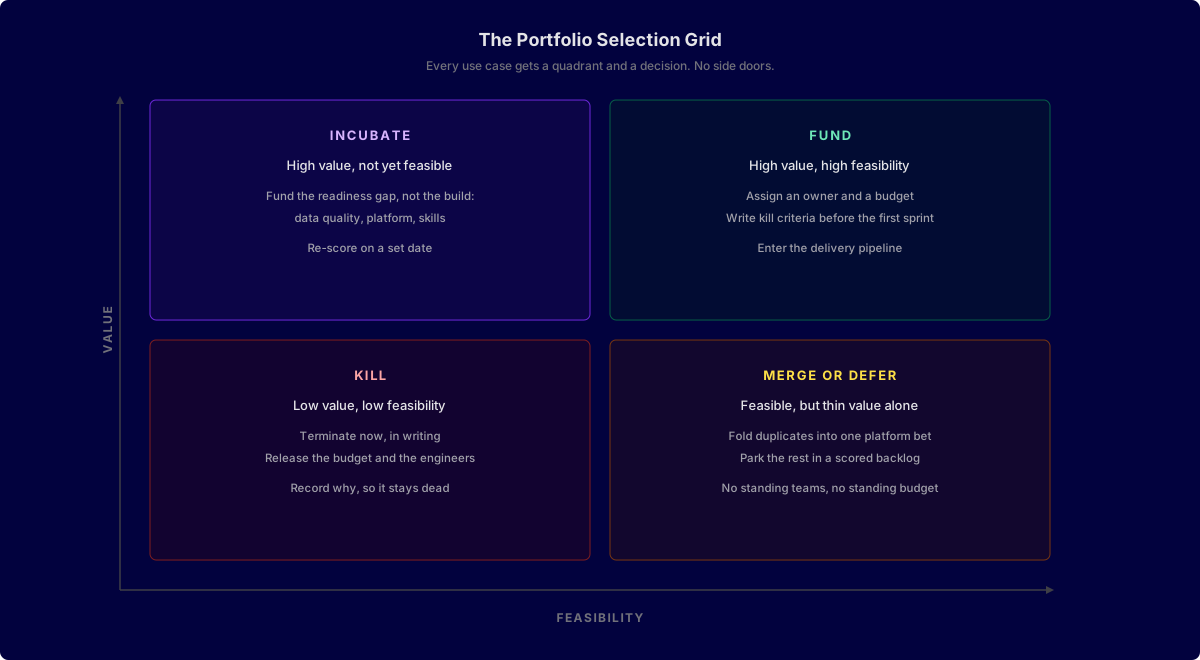
A selection discipline has four parts, and most enterprises have none of them.
A single inventory. Use cases live in one system with owners, status, and scores, not in per-department slide decks. If assembling the full list takes a week of email, there is no inventory.
Explicit scoring dimensions. Value and feasibility, decomposed into dimensions that fit the sector: revenue impact, regulatory exposure, data readiness, execution complexity. The specific dimensions matter less than the fact that they are written down, applied to every candidate, and argued about in the open.
Kill criteria set at funding time. Every funded use case gets the conditions under which it dies, decided before the first sprint. Without pre-committed kill criteria, every review becomes a negotiation with a sponsor defending sunk cost.
A governance cadence. The portfolio gets re-scored and re-decided on a schedule, quarterly at minimum. New candidates enter through the same scoring gate, not through a side door labeled executive sponsorship.
The Kill Decision Is the Product
Funding decisions are easy; enthusiasm does that work for free. The value of portfolio governance concentrates in the kills and the merges.
Killing a pilot releases budget, engineers, and the scarcest resource in any transformation: organizational attention. Merging three near-identical document-intelligence pilots into one platform bet removes two future migration projects before they exist. These are the compounding moves, and they only happen when the whole portfolio is visible in one place and the kill criteria were agreed before politics could form around each initiative.
There is a simple test of whether your organization governs its AI portfolio. Name the last AI initiative you killed on schedule, by pre-agreed criteria, without a sponsor fight. If there is no answer, the portfolio governs you.
What Changes Under Governance
Selection discipline changes the questions leadership asks. “Which pilots look promising?” becomes “what is the portfolio worth, what did we kill this quarter, and what did the kills release?” Budget conversations move from defending line items to rebalancing a scored portfolio. The board question that terrifies technology leaders, “why these bets?”, gets a written answer that predates the meeting.
It also changes what engineering receives. A funded use case arrives with an owner, a scoring rationale, and kill criteria, which means delivery teams inherit clarity instead of a sponsor’s enthusiasm. Selection feeds calibration: the funded backlog is the input to infrastructure assessment, not an afterthought discovered mid-build.
This is what the AI readiness assessment is for: an inventory of your data, candidate use cases and risk exposure, ending in a ranked roadmap with cost and payback for each item, so fund, kill and merge decisions are written down before the budget meeting.
The lottery is comfortable because tickets are cheap and nobody audits the drawer they sit in. Governance is uncomfortable because every quarter it makes someone’s project die in public. That discomfort is the point. It is what a portfolio costs, and it is far cheaper than the alternative: fifty tickets, three winners, and no idea which drawer the losses are in.